
Measuring website visibility in traditional search is something we have been doing for years. We can look at rankings for important queries, check impressions and clicks in Google Search Console, and compare organic performance over time. AI Search is harder to pin down because the answer itself is less stable and the conditions behind it matter more.
Imagine a Melbourne company that manufactures and installs double-glazed windows. It may appear among the recommendations in one AI-generated answer, show up only as a source in another similar test, and be absent from a third. An AI visibility tool might still reduce all of this to a neat number such as 42%.
That number can be useful, but only if we understand what produced it. Before we start tracking AI visibility, we need to know what is being measured, how the test is being run, and whether the same test can be repeated later under comparable conditions. The point is not simply to produce a score today. We need a method that will still mean the same thing when we return to it later.
Why This Article Takes a Different Approach
Many articles about AI visibility begin with the metrics. They focus on mentions, citations, recommendations, share of voice, visibility scores and competitor performance. Modern AI visibility tools can collect much of this automatically and present it in convenient dashboards.
That is a major advantage. Without automation, serious monitoring quickly becomes impractical. Running dozens or hundreds of prompts across several AI systems already creates a large volume of responses to store and compare. Repeating the same work later makes manual tracking even less realistic.
The difficulty comes when the dashboard makes the result look more self-explanatory than it really is. A score of 42% tells us very little unless we know what kind of test produced it. We need to understand the prompt set, the systems included, the way the runs were repeated and the rules used to classify the answers.
The tool may be doing its job perfectly while the user still misunderstands what the result represents.
For that reason, this article starts slightly earlier than the usual discussion of AI visibility metrics. The first question is not which metric to choose, but what needs to be defined before the metric becomes meaningful.
A useful way to think about the process is to separate three levels: observation, metric and interpretation. We first record what happened in individual AI responses. Those observations can then be aggregated into a metric. Only after that do we decide what the resulting number actually tells us.
If a company was recommended in 18 out of 50 tested responses, we can calculate a recommendation rate of 36%. That figure becomes meaningful only when we understand what those 50 tests represented and how they were conducted.
1. What Exactly Are We Observing?
When a company appears in an AI-generated answer, we have learned something useful. Under those particular conditions, the system was able to identify the company and chose to include it in the response. What remains unknown is how regularly the same thing happens.
Each response is therefore one observation rather than a complete picture of the business’s AI visibility. That observation sits inside a particular context:
query × platform or surface × language × geography × run or time
The distinction matters because “double glazing Melbourne” and “Who would you recommend for retrofitting old timber windows with double glazing in Melbourne?” refer to the same broad market but can produce very different answers.
The system being tested can change the result. Language and location can matter as well, and an identical prompt may still produce a different response on another run.
We have explored that variability in more detail in Why Two People Can Receive Different AI Answers.
So before counting anything, we need to be clear about the observations we are actually collecting.
2. The Query Set Matters More Than It Looks
The choice of queries has a major influence on the final result.
For a Melbourne double-glazing company, an obvious test might be “double glazing companies Melbourne”. A potential customer, however, may be more specific and ask “Which companies can retrofit existing timber windows with double glazing?” or “Who would you recommend for double glazing a Victorian house in Melbourne?”
Those questions do not represent the same situation. Someone searching broadly for providers is at a different point from someone who already knows the service they need, and a request for a recommendation introduces another layer again. A useful query set should reflect the situations that matter to the business rather than simply reproduce a keyword list.
Size alone does not make the sample better. A thousand automatically generated prompt variations may look impressive, but if they poorly represent what potential customers actually ask, the resulting dataset will still be weak.
The usefulness of the visibility score depends heavily on the usefulness of the query set behind it.
3. What Counts as Visibility?
Once the query set is defined, we need to decide what kind of appearance matters.
Consider a single AI-generated answer about double glazing in Melbourne. The system may use one company’s website to support a factual point about energy efficiency. It may mention another business simply because it is a local installer. It may then recommend a different company because the user asked specifically about retrofitting timber windows.
All of those businesses are visible, but they are visible in different ways.
This connects with the broader question explored in What Does AI Search Optimization Actually Optimize?, where different forms of AI visibility are treated as distinct outcomes rather than one single event.
A simple visible / not visible flag can still be useful at a basic level. More detailed measurement should preserve enough context to distinguish between being named, being used as a source and being recommended in a relevant situation.
4. Keep the Test Conditions Stable
A business may care about several AI systems, languages or markets, and all of them may be worth testing. The challenge is to preserve enough consistency that the results remain comparable over time.
If one round of measurement uses a particular setup and the next round changes it substantially, the comparison becomes harder to interpret. A different platform mix, a changed geography or a revised query set can move the final score even if nothing about the business itself has changed.
Aggregate visibility scores can still be useful, especially for broad trend reporting. Their value increases when the underlying dimensions remain visible and the method of combining them is clear.
We touched on the same issue in SEO Audit vs AI Search Audit (Yes, Another One): bringing different types of visibility into one reporting environment does not automatically make them directly comparable.
5. One Test Is Not Enough
AI responses vary from one run to another. A company may appear in one answer and disappear in the next; recommendation order and citations can change as well.
A single test therefore gives us a useful but narrow piece of evidence. It tells us what happened once under a particular set of conditions. To see whether the same outcome appears consistently, we need repetition.
There is no universal number of runs that suits every measurement exercise. The appropriate level depends on the scale of the test and the level of stability we need from the result. A small, carefully controlled query set may be handled differently from a much larger monitoring programme.
What matters is that repeated testing begins to reveal patterns that a single response cannot.
6. Compare with Competitors
A visibility rate becomes much easier to understand when it is placed in a competitive context.
If a company appears in 28% of relevant responses, that number means little on its own. It looks strong if major competitors appear much less often and much weaker if they appear in more than half of the same tests.
The comparison becomes more useful when we look beyond the overall percentage. Our Melbourne company might be cited frequently in informational answers because its website contains strong educational content about double glazing, while another installer appears much more often in direct recommendation queries. The same company may perform well for broad Melbourne searches yet struggle to appear when the discussion turns to heritage homes or timber-window retrofits.
That kind of comparison shows where the business is strong and where the visibility gap actually sits.
7. Establish a Baseline — and Repeat It
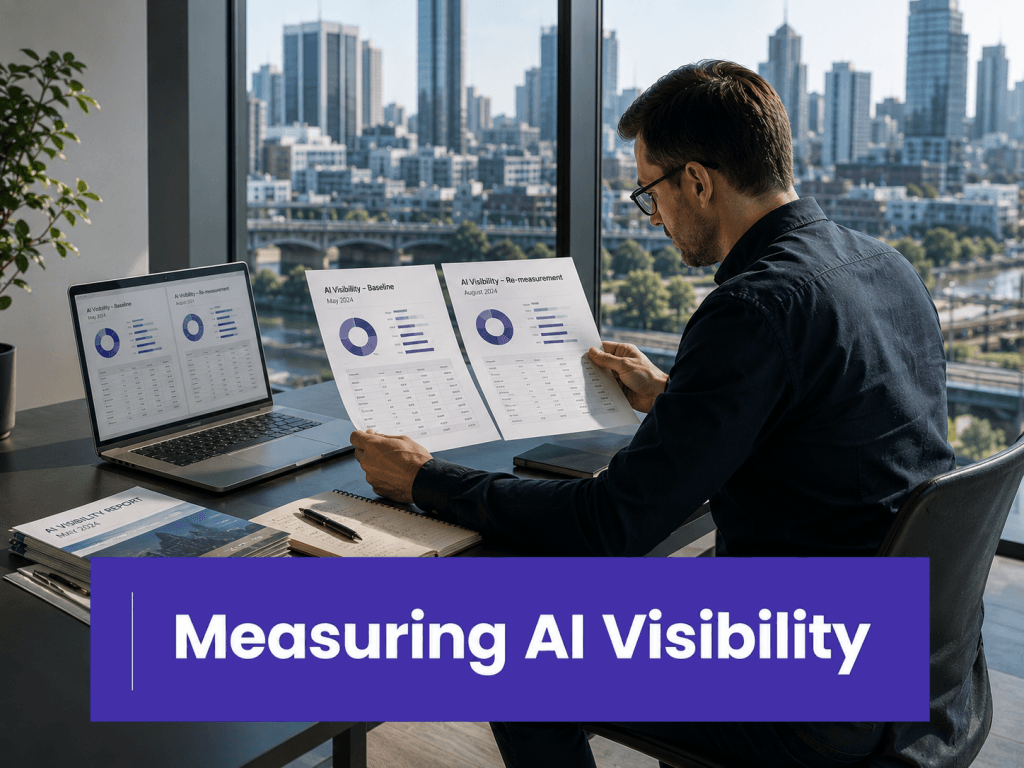
The first serious measurement should create a baseline that can be reproduced later.
That does not require turning the setup into another long checklist. What matters is that the conditions are documented well enough to recreate the same test. The query set should remain identifiable, the same measurement surfaces should be used where possible, and the way responses are classified should not drift without a clear reason.
A month later, the same measurement can be run again under comparable conditions.
This is where the method becomes genuinely useful. During that month, the business may have clarified its services on the website, corrected inconsistent company information, published new pages or gained stronger third-party mentions. If the measurement setup remains stable, the next test can show whether the observed pattern changed.
Instead of saying “Our AI visibility is 42%”, we can say something more useful, such as “Using the same measurement setup, recommendation frequency increased from 24% to 37%”.
That statement is stronger because the comparison has a stable reference point.
This baseline-and-retest logic also appears in What Does an AI Search Optimization Agency Actually Do?, where establishing a starting point and testing again after implementation are part of the wider optimisation process.
8. Don’t Throw Away the Raw Answers
Dashboards are good at turning complex AI responses into structured data, and that is essential if we want to work at scale. Some context will inevitably be lost in that process.
A tool might record a successful mention while the underlying answer incorrectly describes a Melbourne company as Sydney-based. Another response may identify the location correctly but misrepresent what the business actually specialises in. Both can still contribute positively to a visibility score even though the business would not regard them as equally successful outcomes.
The original responses therefore remain useful after classification. They show whether the AI is representing the business accurately and whether the apparent visibility is actually useful in context.
Large-scale monitoring still depends on automation; manually reviewing every response would defeat much of the purpose of using a tool. Periodic human review serves a different role. It checks whether the structured metrics still correspond to what is happening in the answers themselves.
Without that check, a measurement can become very precise while drifting away from the thing it was intended to describe.
9. Tools Are Part of the Solution
AI visibility tools become more valuable as the measurement becomes more serious. They can handle large numbers of queries, repeat tests, store responses, collect citations, compare competitors and show changes over time. Managing all of that manually soon becomes inefficient.
Their output still depends on methodological choices. A visibility score reflects a particular way of selecting prompts, running tests and classifying the resulting answers.
That is why two tools can give the same company different scores without either of them necessarily being wrong. They may simply be looking at different samples or applying different rules.
The dashboard is best treated as part of the investigation rather than its endpoint. It gives us the scale and consistency that manual testing cannot provide. The methodology is what allows us to understand the result well enough to use it.
10. From Numbers to Decisions
By this point, the purpose of the measurement should be clearer. The goal is not to produce the most authoritative-looking percentage. It is to create evidence that helps us decide whether something important is changing.
A mention rate of 34% may be encouraging, but the percentage alone does not tell us much about business impact. Its value depends on whether the company is appearing in the situations that matter. If visibility is improving mainly in generic informational answers, that may be useful. If the improvement is concentrated in relevant recommendation queries, it may deserve more attention.
This is the point at which measurement becomes part of decision-making. The number gives us a signal, and the surrounding evidence tells us how seriously to take it.
Conclusion
AI visibility is best understood as a pattern observed under defined conditions rather than a score that exists somewhere waiting to be discovered.
Once we think about it that way, the purpose of measurement changes. The first measurement gives us a starting point. Its real value appears when we return later and can see whether the pattern has changed.
That is why reproducibility matters so much. A measurement becomes more valuable when we can return to it later and still understand what we are comparing. If the method keeps changing, the numbers may look precise while becoming less useful.
Tools make this practical at scale, and human review keeps the measurements connected to the meaning of the underlying answers. Together, they give us a much stronger basis for tracking AI visibility than isolated prompts or unexplained dashboard scores.
Even then, there are limits. Some parts of AI Search remain difficult to observe directly, and some conclusions are much harder to support than others.
That is the subject of the next article: What We Still Cannot Reliably Measure in AI Search.